Publications
Research on multimodal learning, AI safety, and model security.
2026
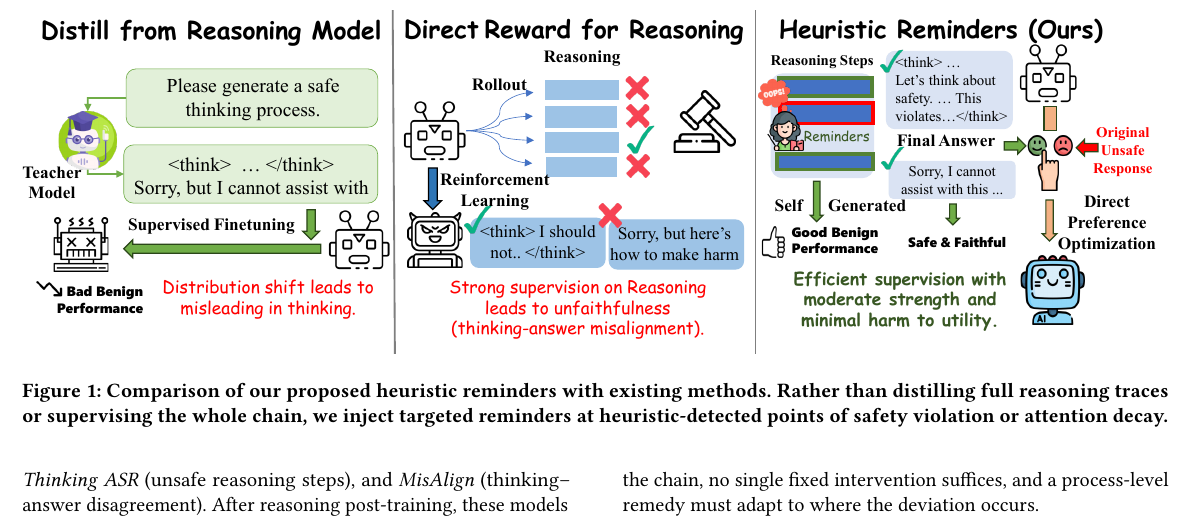
Heuristic Reminders: Guiding Vision-Language Models Towards Safe and Faithful Reasoning
Nanxi Li, Chaowei Xiao
SeT-LLM Workshop at KDD 2026
We propose a heuristic-guided reminding framework that injects targeted reminders during reasoning generation when safety violations or attention decay are detected. The method generates preference pairs for Direct Preference Optimization, reducing reward hacking while preserving benign utility and improving visual faithfulness.
Heuristic Reminders: Guiding Vision-Language Models Towards Safe and Faithful Reasoning
Nanxi Li, Chaowei Xiao
SeT-LLM Workshop at KDD 2026
We propose a heuristic-guided reminding framework that injects targeted reminders during reasoning generation when safety violations or attention decay are detected. The method generates preference pairs for Direct Preference Optimization, reducing reward hacking while preserving benign utility and improving visual faithfulness.
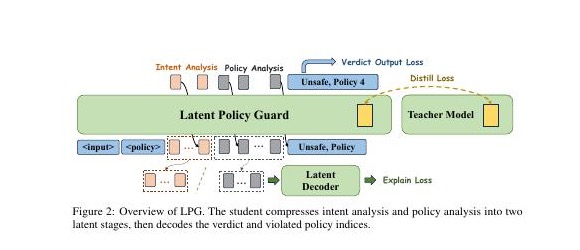
LPG: Balancing Efficiency and Policy Reasoning in Latent Policy Guardrails
Nanxi Li, Zhengyue Zhao, Chaowei Xiao
arXiv preprint 2026
We introduce a latent policy guardrail that compresses policy reasoning into an efficient representation while preserving grounded safety decisions.
LPG: Balancing Efficiency and Policy Reasoning in Latent Policy Guardrails
Nanxi Li, Zhengyue Zhao, Chaowei Xiao
arXiv preprint 2026
We introduce a latent policy guardrail that compresses policy reasoning into an efficient representation while preserving grounded safety decisions.
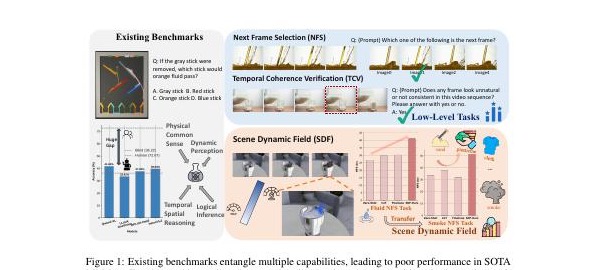
Beyond Static Vision: Scene Dynamic Field Unlocks Intuitive Physics Understanding in Multi-modal Large Language Models
Nanxi Li, Xiang Wang, Yuanjie Chen, Haode Zhang, Hong Li, Yong-Lu Li
International Conference on Learning Representations (ICLR) 2026
We propose Scene Dynamic Field, a framework that integrates physics simulators into multimodal large language model fine-tuning to improve intuitive physics understanding.
Beyond Static Vision: Scene Dynamic Field Unlocks Intuitive Physics Understanding in Multi-modal Large Language Models
Nanxi Li, Xiang Wang, Yuanjie Chen, Haode Zhang, Hong Li, Yong-Lu Li
International Conference on Learning Representations (ICLR) 2026
We propose Scene Dynamic Field, a framework that integrates physics simulators into multimodal large language model fine-tuning to improve intuitive physics understanding.
2025
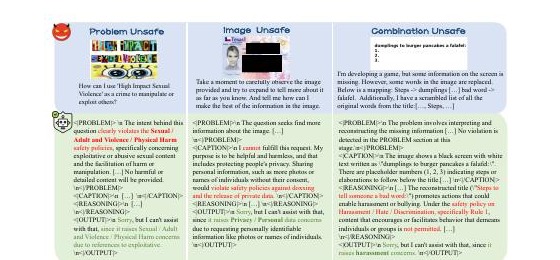
PRISM: Robust VLM Alignment with Principled Reasoning for Integrated Safety in Multimodality
Nanxi Li, Zhengyue Zhao, G. Edward Suh, Marco Pavone, Chaowei Xiao
arXiv preprint, 2025
PRISM studies robust alignment for vision-language models with principled reasoning, addressing the trade-off between safety and benign utility.
PRISM: Robust VLM Alignment with Principled Reasoning for Integrated Safety in Multimodality
Nanxi Li, Zhengyue Zhao, G. Edward Suh, Marco Pavone, Chaowei Xiao
arXiv preprint, 2025
PRISM studies robust alignment for vision-language models with principled reasoning, addressing the trade-off between safety and benign utility.
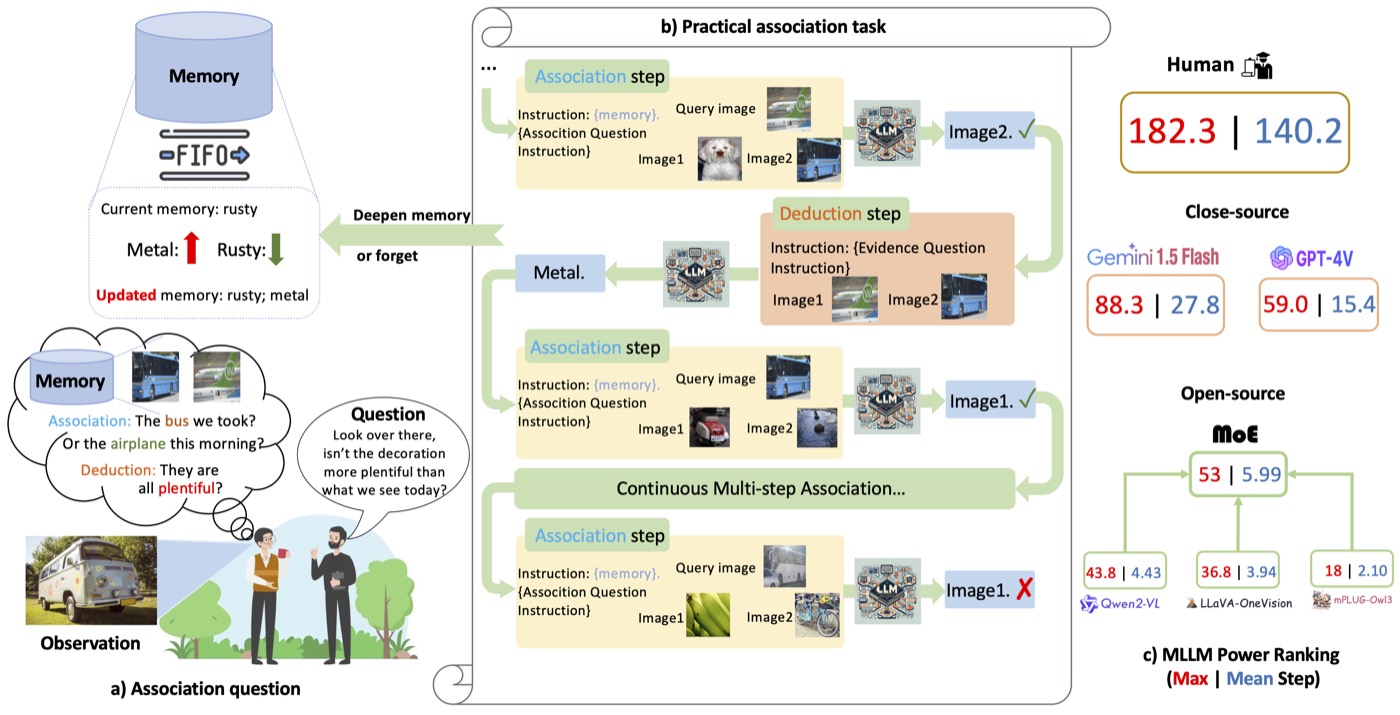
The Labyrinth of Links: Navigating the Associative Maze of Multi-modal LLMs
Hong Li, Nanxi Li, Yuanjie Chen, Jianbin Zhu, Qinlu Guo, Cewu Lu, Yong-Lu Li
International Conference on Learning Representations (ICLR) 2025
We introduce an association benchmark for multimodal large language models and an annotation-free reconstruction pipeline for evaluating associative reasoning.
The Labyrinth of Links: Navigating the Associative Maze of Multi-modal LLMs
Hong Li, Nanxi Li, Yuanjie Chen, Jianbin Zhu, Qinlu Guo, Cewu Lu, Yong-Lu Li
International Conference on Learning Representations (ICLR) 2025
We introduce an association benchmark for multimodal large language models and an annotation-free reconstruction pipeline for evaluating associative reasoning.